The gist: This post used to compare Kimi K2 and Claude Sonnet 4.5, where Kimi was the cheap option. Both models have been replaced, and the price gap now runs the other way. Claude Sonnet 5.5 lists at $2 input and $10 output per million tokens. Kimi K3 lists at $3 input and $15 output, so the same tokens cost 1.5 times as much on K3. Cost per task also depends on how many tokens each model spends. Artificial Analysis, a third party, lists K3 (Max) at 160M output tokens and $2.00 per Intelligence Index task and Sonnet 5.5 (Max) at 420M output tokens and $7.67 per task, but its two pages use different model sets and index scores, so treat those figures as third-party data that is not directly comparable. The published coding scores for the two models come from different benchmark versions, so they cannot be ranked.
- Claude Sonnet 5.5 was released September 28, 2026. API pricing is $2 per million input tokens, $10 per million output tokens, and $0.20 per million cache-read tokens. Cache writes are $2.50 per million for the 5-minute tier and $4.00 for the 1-hour tier.
- Claude Sonnet 5.5 has a 1M-token context window and up to 128K output tokens (model ID claude-sonnet-5-5), per Anthropic's models overview.
- Kimi K3 was announced July 16-17, 2026. Moonshot's global platform lists $3 per million cache-miss input tokens, $0.30 cache-hit input, and $15 output in USD. The same rates in CNY are 20, 2, and 100 yuan. Cache writes are $3.00 (5-minute) and $6.00 (1-hour) in USD.
- Kimi K3 has 2.8 trillion total parameters, 104 billion active, a 1,048,576-token context window, and released weights (July 27, 2026).
- Moonshot reports 88.3 for Kimi K3 on Terminal-Bench 2.1. Anthropic reports 70.6% for Claude Sonnet 5.5 on Terminal-Bench 4.0. The versions differ, so the scores are not comparable.
- Anthropic says Sonnet 5.5 runs 30%+ faster than Sonnet 5 and costs up to 30% less for most work.
The original version of this post asked whether Kimi K2 at $2.50 per million output tokens was worth trading Claude Sonnet 4.5 at $15 for. Neither model is current. The question still matters, but the numbers changed: the premium option got cheaper and the budget option got more expensive. Anthropic deprecated Sonnet 4.5 on September 30, 2026 (retirement November 30, 2026, replacement claude-sonnet-5-5), and Kimi K2 was discontinued on May 25, 2026, so both models in the old comparison have been replaced. This update recomputes the cost side from each provider's own pages.
This post covers cost per coding task only. For the full model lineup by task, see the task-by-task model guide. For K3 itself (architecture, open weights, launch benchmarks), see the Kimi K3 review.
Price per token
The gap reversed. Sonnet 5.5 is now the cheaper list price.
API list prices per 1M tokens, October 3, 2026
| Claude Sonnet 5.5 (USD) | Kimi K3 (USD, global platform) | Kimi K3 (CNY) | |
|---|---|---|---|
| Input | $2 | $3 | 20 yuan |
| Cached input (cache read) | $0.20 | $0.30 | 2 yuan |
| Cache write, 5-minute | $2.50 | $3.00 | Not shown here |
| Cache write, 1-hour | $4.00 | $6.00 | Not shown here |
| Output | $10 | $15 | 100 yuan |
| Context window | 1M | 1,048,576 tokens | 1,048,576 tokens |
Source: Anthropic's Sonnet 5.5 announcement and pricing page; Moonshot's USD rate card and Kimi K3 announcement. Moonshot's global platform prices K3 in USD ($3.00 / $0.30 / $15.00), and the CNY column is the equivalent rate card (20 / 2 / 100 yuan). Neither column is converted from the other here.
On input, cached input, and output rates, K3 is exactly 1.5 times the Sonnet 5.5 price ($3 against $2, $0.30 against $0.20, $15 against $10). Cache writes are different: K3 is 1.2 times Sonnet 5.5 on the 5-minute tier ($3.00 against $2.50) and 1.5 times on the 1-hour tier ($6.00 against $4.00). For output, Kimi K2 at $2.50 was about 6x cheaper than Sonnet 4.5 at $15, and that gap is gone for these two models.
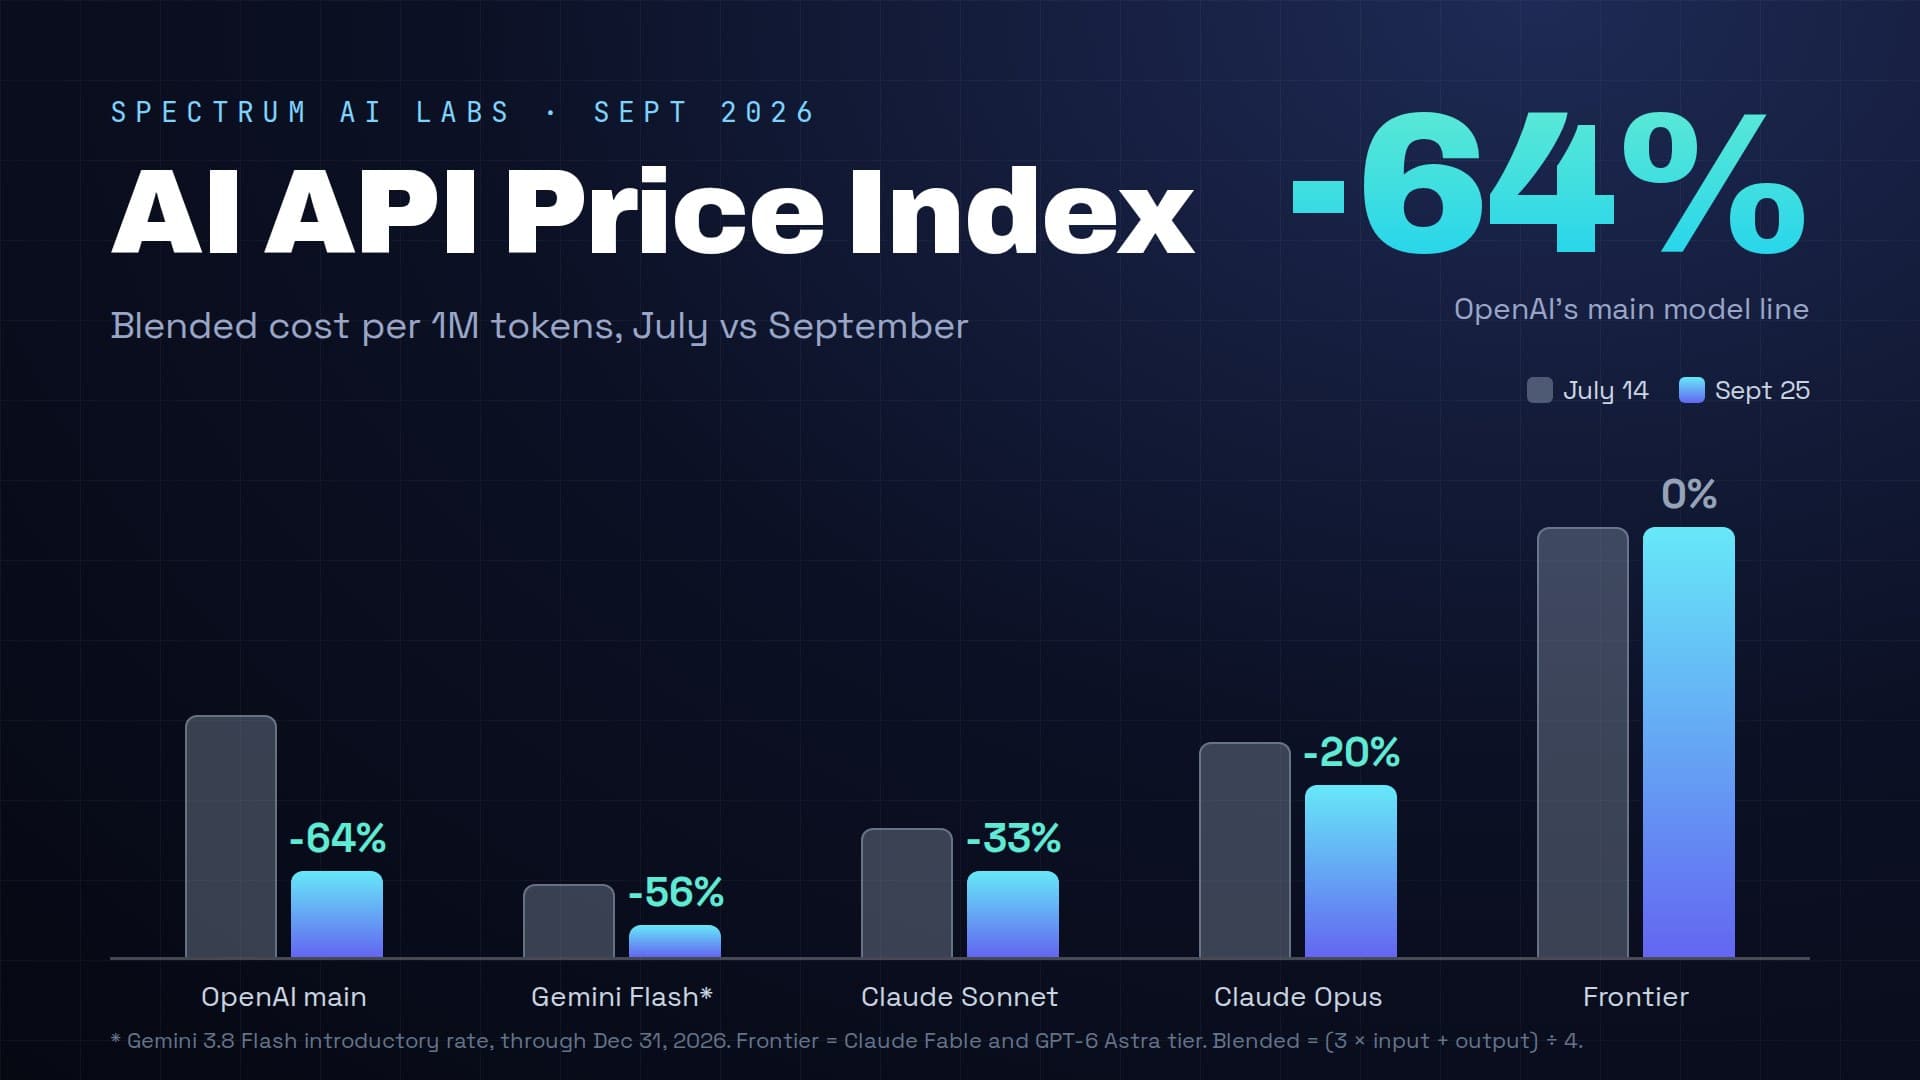
If you track prices across providers, the AI API price index shows where both sit among the other current models.
Cost per task
Worked arithmetic on one illustrative coding task.
The table below uses an assumed task, not a measurement: an agentic coding run that reads 200,000 input tokens and writes 20,000 output tokens. Swap in your own numbers. The "with caching" rows assume 90% of the input is served from cache, which is also an assumption. Real hit rates vary by workflow. The cached rows count cache reads only and leave out cache-write cost, so they assume a warm cache and understate both bills.
One task: 200K input tokens, 20K output tokens
| Scenario | Claude Sonnet 5.5 (USD) | Kimi K3 (USD) | Kimi K3 (CNY) |
|---|---|---|---|
| No caching, one task | $0.60 | $0.90 | 6.00 yuan |
| 90% of input cached, one task | $0.276 | $0.414 | 2.76 yuan |
| No caching, 100 tasks | $60 | $90 | 600 yuan |
| 90% cached, 100 tasks | $27.60 | $41.40 | 276 yuan |
Source: Computed from the list prices above. Token counts and cache rate are assumptions for illustration. Cache-write cost is not included in the cached rows.
At equal token counts the ratio is 1.5x across input, cached input, and output rates. Once cache writes count, the gap on that part of the bill is 1.2x to 1.5x, so the overall ratio is no longer a flat 1.5x. So the useful question is not "which is cheaper per token" but "how many tokens does each one burn to finish the same task."
Tokens per task
A 1.5x price gap only holds if both models use the same number of tokens.
K3 would need to finish a task using less than two thirds of the tokens Sonnet 5.5 uses to come out even on the rates above. Third-party data now lists both models:
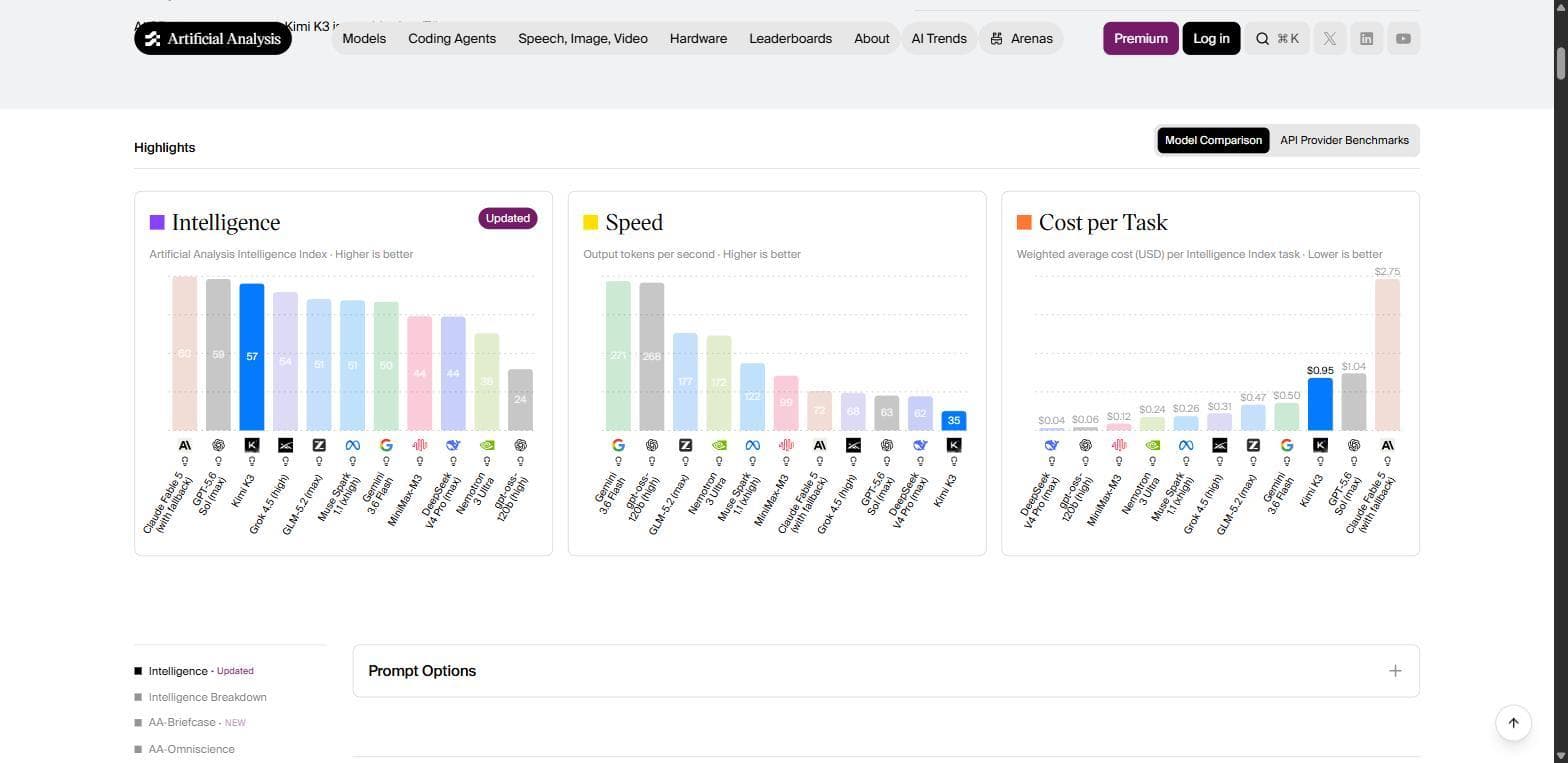
- Artificial Analysis, a third-party benchmarking site, lists K3 (Max) at 160 million tokens and $2.00 per Intelligence Index task. It lists Sonnet 5.5 (Max) at 420 million tokens and $7.67 per task. They come from Artificial Analysis's own task mix, not from your coding workload, so read them as third-party data rather than a verdict.
- The data is mixed and not directly comparable. The two Artificial Analysis pages show different model-set sizes (118 against 224) and different index scores (44 against 56), so the per-task figures were not measured against the same set of models or on the same scale.
- Anthropic says Sonnet 5.5 "costs up to 30% less for most work" than Sonnet 5, at the same per-token price. That is a claim about its predecessor, not about K3.
Not sure which AI model to use?
21 models · Personalized picks · 60 seconds
Measure it on your own repo
Run the same five to ten real tasks through both models and record input and output tokens per finished task, including retries. Multiply by the list prices above. That number will tell you more than any published average, and it takes an afternoon.
Speed also affects cost indirectly. In launch-period Artificial Analysis testing quoted in our K3 review, K3 measured 35 output tokens per second, the slowest of the major flagships then. Anthropic says Sonnet 5.5 generates output 30%+ faster than Sonnet 5, but it has not published a tokens-per-second figure we can compare directly. For interactive coding, waiting on output is a real cost even though it never shows up on the invoice.
Coding benchmarks
Each provider reports a different benchmark version, so the scores don't rank the models.
Published coding results, each from its own provider
| Model | Benchmark and version | Score | Reported by |
|---|---|---|---|
| Kimi K3 | Terminal-Bench 2.1 (Kimi Code harness) | 88.3 | Moonshot AI |
| Claude Sonnet 5.5 | Terminal-Bench 4.0 | 70.6% | Anthropic |
Source: Moonshot AI Kimi K3 announcement; Anthropic Claude Sonnet 5.5 announcement. Terminal-Bench scores depend on the harness and the benchmark version.
These two rows are not a head-to-head. Terminal-Bench 2.1 and 4.0 are different test sets, and the results also depend on the harness each lab used. Anthropic's own announcement compares Sonnet 5.5 with Sonnet 5, which scored 10.3% on version 4.0, so the jump it shows is the improvement over its predecessor. Neither lab has published a score for the other's model on a shared version that we could verify.
We also found no SWE-bench score for Sonnet 5.5 on Anthropic's announcement page, and no matching SWE-bench figure for K3. So this post leaves SWE-bench out rather than guess. The old post's SWE-bench numbers (77.2% and 71.3%) belonged to Sonnet 4.5 and Kimi K2 Thinking and should not be carried over to the current models.
Which to pick
Start from the task, then check the token count.
Sonnet 5.5 is the default if
- You pay by the token and want the lower list price. Its input, cached input, and output rates are one third lower than K3's, which costs 1.5 times as much on those rates.
- You want faster output in interactive coding, since Anthropic reports a 30%+ speedup over Sonnet 5 and K3 was the slowest flagship in launch testing.
- You want predictable spend. Anthropic publishes cache read and write prices alongside the base rates.
Kimi K3 is worth testing if
- You need open weights, whether to host the model yourself, fine-tune it, or inspect it. Moonshot released them on July 27 under the Kimi K3 License. Self-hosting a 2.8T-parameter model takes serious infrastructure, so most teams will still use the API.
- You run long autonomous coding jobs where latency per step matters less than finishing the work. The K3 review covers the launch benchmarks and where K3 lost to other models.
- Your own task measurements show it finishing with enough fewer tokens to offset the 1.5x list rate.
A cheap way to decide
- 1Pick five to ten real tasks from your backlog, including at least one multi-file change.
- 2Run each through both models with the same prompt, and log input tokens, output tokens, and whether it passed your tests.
- 3Price the logs at the list rates above, with your actual cache hit rate, and compare cost per passing task.
You can plug your own token counts into the AI cost calculator, or use the model picker if you want a shortlist across providers.
Sources
Prices and benchmark scores trace to these pages, checked October 3, 2026.
- Anthropic: Introducing Claude Sonnet 5.5 (pricing, Terminal-Bench 4.0, speed and cost claims)
- Anthropic: models overview (claude-sonnet-5-5, 1M context, 128K max output)
- Anthropic: pricing (cache read and write rates)
- Moonshot AI: API pricing, USD rate card (cache-hit, cache-miss, output, cache write)
- Moonshot AI: Kimi K3 announcement ($0.30/MTok cache-hit input, $3.00/MTok cache-miss input, $15.00/MTok output; Terminal-Bench 2.1 score)
- Moonshot AI: official Kimi K3 model card
- Artificial Analysis (third party) model pages for K3 (Max) and Sonnet 5.5 (Max): 160M output tokens and $2.00 per Intelligence Index task for K3, 420M output tokens and $7.67 for Sonnet 5.5. The two pages use different model sets (118 and 224) and index scores (44 and 56).
- Artificial Analysis launch-period speed figure for K3 (35 output tokens per second) is quoted from our Kimi K3 review, which captured it on July 23, 2026.
FAQ
Is Kimi K3 cheaper than Claude Sonnet 5.5?
Not per token. Claude Sonnet 5.5 lists at $2 input and $10 output per million tokens. Moonshot's global platform lists Kimi K3 at $3 input, $15 output, and $0.30 cached input in USD (the same rates in CNY are 20, 100, and 2 yuan). On input, cached input, and output rates, K3 costs 1.5 times as much. Cost per task also depends on how many tokens each model uses to finish the job. Artificial Analysis, a third party, lists K3 (Max) at 160M output tokens and $2.00 per Intelligence Index task and Sonnet 5.5 (Max) at 420M output tokens and $7.67 per task, but its two pages use different model sets and index scores, so treat those figures as third-party data that is not directly comparable.
Which scores higher on coding benchmarks, Kimi K3 or Claude Sonnet 5.5?
The published numbers cannot be ranked against each other. Moonshot reports 88.3 for Kimi K3 on Terminal-Bench 2.1, and Anthropic reports 70.6% for Claude Sonnet 5.5 on Terminal-Bench 4.0. These are different benchmark versions, so the two scores do not measure the same thing.
Do Kimi K3 and Claude Sonnet 5.5 have the same context window?
They are in the same range. Kimi K3 lists a 1,048,576-token context window on its model card, and Claude Sonnet 5.5 has a 1M-token context window with up to 128K output tokens according to Anthropic's models overview.
Can I self-host Kimi K3 to save money?
Moonshot released the K3 weights on July 27, 2026, but the model has 2.8 trillion total parameters (104 billion active), so it needs data-center hardware. For most teams the API is the realistic route, and Sonnet 5.5 is not available as open weights.
Founder of Spectrum AI Labs — testing AI tools and models, and writing up what actually ships.
More about Paras →Need Help Choosing the Right AI Model?
We help engineering teams select and implement AI coding tools that match their budget and requirements. Get a free consultation to explore what's possible for your specific use case.