The gist: Prompting the GPT-6 family is mostly about saying less, more clearly. Define the outcome and what counts as done, state each rule once, name the actions the model can take without asking, and ask for short progress updates on long tasks (my recommendation). Use the Responses API to carry reasoning forward and the reasoning effort setting to trade speed for depth. One caveat: OpenAI scopes its warning about overly specific guidance to Astra ("Guidance that helps Sol or Luna may overconstrain GPT-6 Astra"), so I treat shorter prompts as a hypothesis to test on Sol and Luna. I would drop the GPT-5-era habit of tuning autonomy and reasoning through prompt wording.
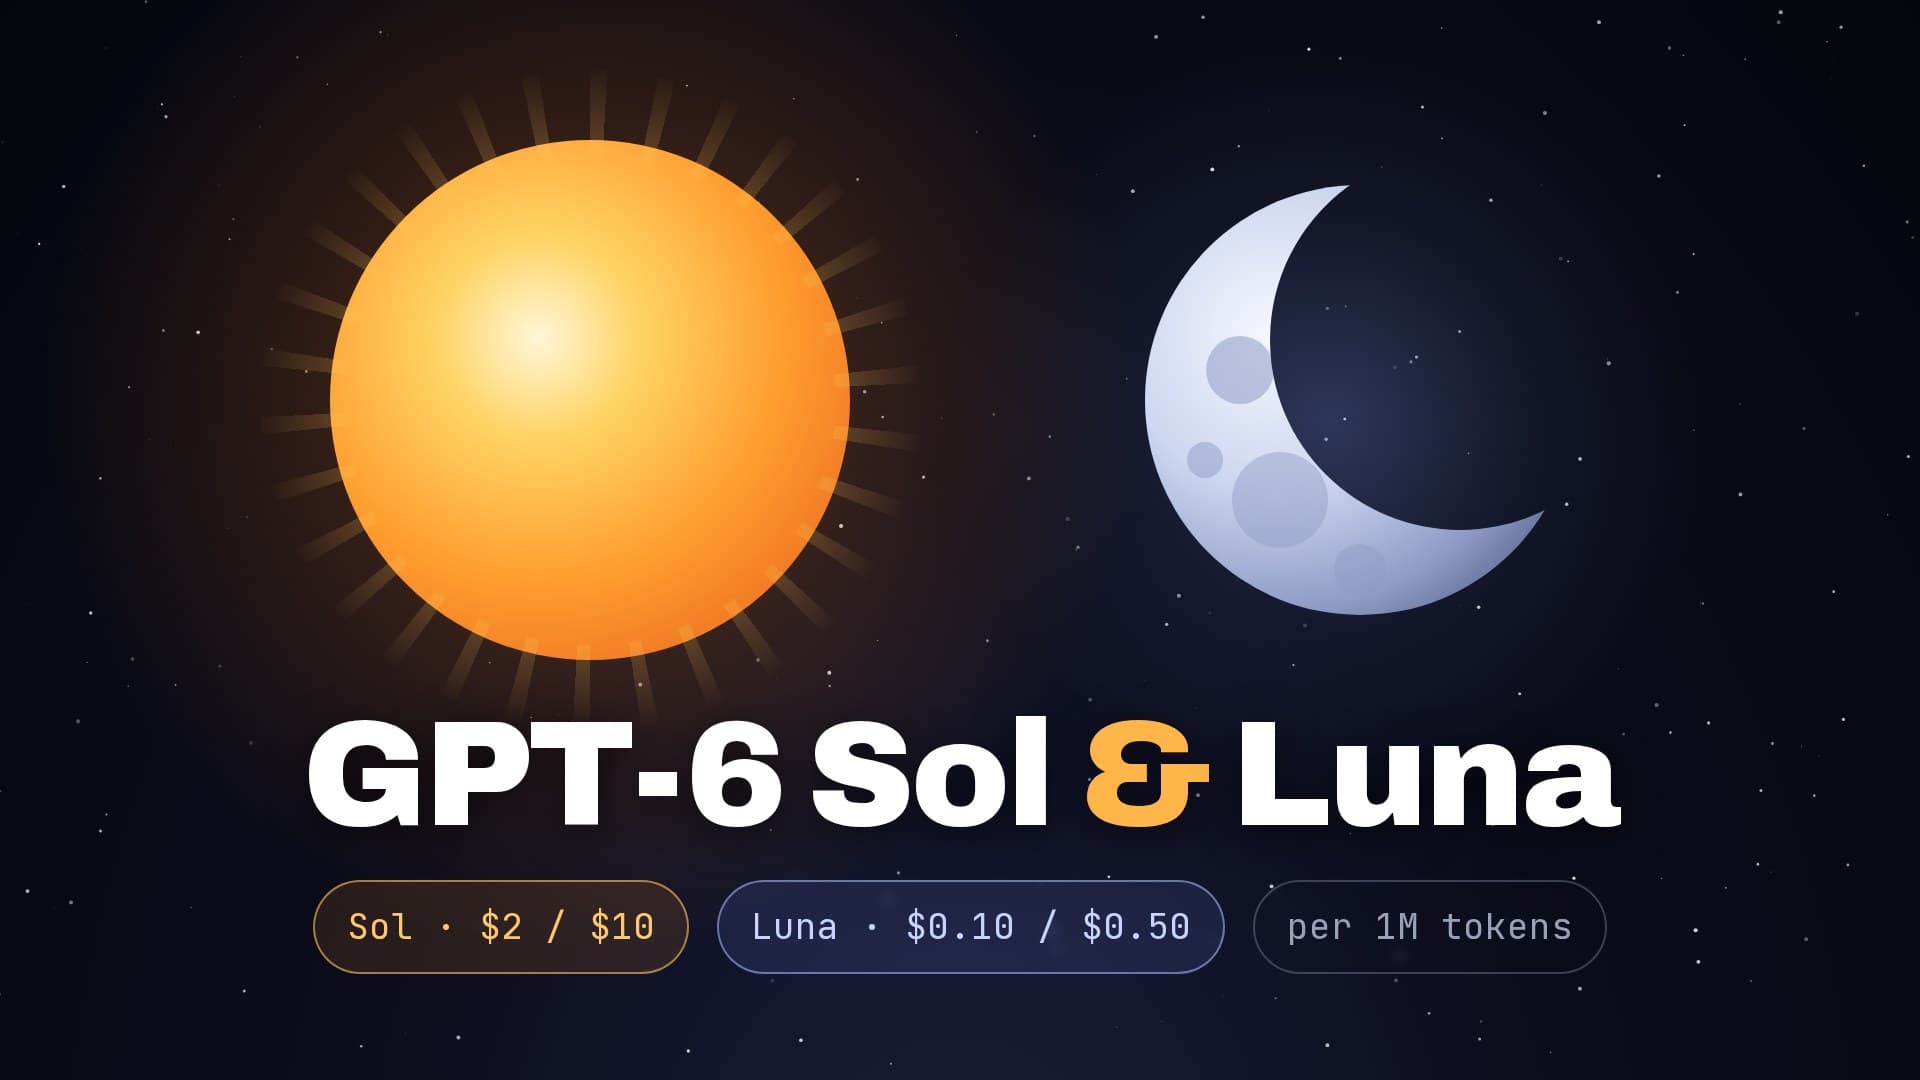
- Current OpenAI models: GPT-6.1 Sol ($2 input / $10 output per 1M tokens), GPT-6 Sol ($2 / $10), GPT-6 Luna ($0.10 / $0.50) and GPT-6 Astra ($10 / $50), at standard rates for prompts up to 272K tokens
- OpenAI warns that guidance that helps Sol or Luna may overconstrain GPT-6 Astra, so overly specific prompts are an Astra-scoped concern that I test on Sol and Luna
- GPT-6.1 Sol reasoning effort supports low, medium (default), high, xhigh and max. It does not support none or minimal
- GPT-6 Sol and Luna support reasoning effort from none up to max, with medium as the default
- Tool calling on GPT-6.1 Sol requires the Responses API; Chat Completions has no tool calling for this model
- I changed or replaced my GPT-5 patterns for agentic eagerness limits, a Plan-Act-Reflect loop, minimal reasoning and markdown rules below. This is editorial; OpenAI has not declared any GPT-5 pattern dropped
This post first appeared in August 2025 as seven patterns for GPT-5. I rewrote it for the GPT-6 family after checking what OpenAI now recommends. Some patterns survived, some changed shape, and I dropped some.
The patterns below apply to GPT-6.1 Sol, GPT-6 Sol, GPT-6 Luna and GPT-6 Astra. Some of OpenAI's published guidance is written specifically for Astra. Where that is the case, I say so, and I treat it as a hypothesis to test on Sol and Luna rather than a guarantee. For which model to pick and what each costs, see the task-by-task AI model guide and the GPT-6 Sol and Luna guide.
What changed since the GPT-5 version
I dropped, replaced or folded five of the original seven patterns into others. This is my editorial call. OpenAI has not declared any GPT-5 pattern dropped.
What we changed from the 2025 GPT-5 patterns
| 2025 pattern | What we changed | Why |
|---|---|---|
| Agentic eagerness (cap at two discovery actions) | Replaced by patterns 1 to 3 | OpenAI warns that guidance that helps Sol or Luna may overconstrain Astra. I state the goal, done criteria and safe actions instead of tuning exploration. |
| Plan-Act-Reflect loop | Dropped from my advice | The original post gave no source for it, and I did not find it in OpenAI's GPT-6 guidance, so I no longer present PAR as a requirement. Pattern 4 covers planning, preambles and a TODO list as my own recommendation. |
| Minimal reasoning in the prompt | Replaced by pattern 6 | Reasoning depth is an API setting. OpenAI's migration advice is to replace minimal with low through the API parameter. GPT-6.1 Sol does not support none or minimal at all, and its lowest setting is low. |
| Markdown discipline rules | Rewritten as pattern 7 | OpenAI's guidance now focuses on stating the writing style and structure you want. |
| Tool preambles | Kept, latency UX tip; not part of OpenAI's GPT-6 prompting list | The preamble wording comes from the GPT-5.5 section of OpenAI's Using GPT-6 page, framed as time-to-first-token UX (pattern 4). |
| Reuse reasoning with the Responses API | Kept (pattern 5) | Still supported, and tool calling on GPT-6.1 Sol now requires Responses. |
| Coding quality rules | Folded into pattern 7 | Calibrate checks to the size of the change. In my own practice, style rules go in a repo file such as AGENTS.md. That is my advice, not a list from OpenAI. |
Source: Spectrum AI Labs editorial comparison of the August 2025 post against OpenAI's current guidance for the GPT-6 family, checked October 3, 2026. OpenAI has not declared any GPT-5 pattern dropped.
One API detail also changed. OpenAI's model guidance lists temperature, top_p and top_logprobs as unsupported when reasoning effort is anything other than none. If a GPT-5-era prompt or wrapper depended on sampling parameters to control behavior, plan to control it through the prompt and the reasoning effort instead.
Pattern 1: Define the assignment and what done means
OpenAI's first tip for the family is a clear assignment, not a clever one.
OpenAI's model guide says to state the result you want, who it is for, the relevant context and constraints, and what counts as done. For Astra, OpenAI's Astra blog adds that the model can be tentative about how far to take a task and sometimes needs a push to keep going. The fix is to put the finish line in the request. If done includes running the code, inspecting the result and fixing failures, say that.
Goal: Fix the failing checkout test.

Done means:
- The failing test passes and the checkout test suite is green.
- You ran the changed code path and checked the output.
- Your final message lists the files you changed and anything I should review.
This replaces the old "agentic eagerness" dial. Instead of telling the model how much to explore, you tell it what finished looks like and let it decide how to get there.
Pattern 2: Trim the scaffolding and state each rule once
Prompts written for weaker models often work against stronger ones.
OpenAI's guidance for Astra says that what used to take a lot of handholding no longer does, and warns that "Guidance that helps Sol or Luna may overconstrain GPT-6 Astra." That caveat is scoped to Astra. I apply it to Sol and Luna as a hypothesis to test, not as OpenAI's word for the whole family. The Astra guidance recommends short skill descriptions, a minimal router document when a skill has several workflows, and an AGENTS.md that does not push the model to review the whole project before every change.
In practice, go through an old GPT-5 prompt and delete anything that exists only to compensate for the model: numbered procedures it would follow anyway, repeated warnings, and long lists of edge cases. Then rerun your evals. If a deleted line mattered, the eval will show it, and you can add back that one line.
Pattern 3: Name the safe actions and set decision boundaries
Repeated "ask first" language can cause needless approval requests.
This advice comes from the GPT-5.6 section of OpenAI's Using GPT-6 page ("Define autonomy and approval boundaries"), not from a GPT-6 section. It recommends naming safe local actions explicitly, such as reading files, inspecting logs, editing in-scope code and running tests. It says to keep the policy in one place and state each rule once, because repeating instructions like "ask first," "do not mutate" or "wait for approval" can trigger approval requests for actions that are safe and expected. I apply it to the GPT-6 family as my own recommendation. For Astra, which OpenAI calls its most aligned model, OpenAI's Astra guidance also suggests revisiting strong language you added to stop other models from acting without permission.
You may do these without asking: read files, search the repo, run tests
and linters, and edit files under src/checkout.

Ask first before: changing dependencies, editing CI config, touching
files outside src/checkout, or deleting data.
Why this replaces 'low eagerness'
The 2025 version limited the agent to two discovery actions. A boundary based on what the agent may touch is easier to reason about, and it does not cut off the exploration the task needs.
Pattern 4: Ask for preambles, a plan and a TODO list on long tasks
This pattern survived from 2025 as my recommendation. It is not part of OpenAI's GPT-6 prompting list.
For agentic and long-running work, I recommend three habits: plan the task so it is fully resolved, send a short preamble before the first tool call, and keep a TODO list to track progress. These are my recommendations. They are not a list from OpenAI's GPT-6 prompting guidance. The preamble wording comes from the GPT-5.5 section of OpenAI's Using GPT-6 page, which asks for a brief visible update that acknowledges the request and states the first step, kept to one or two sentences. OpenAI frames that as a time-to-first-token UX tip, so treat it as a responsiveness choice. The idea that these updates make a long run easier to supervise, in coding and non-coding work alike, paraphrases OpenAI's archived GPT-5.1 guide.
Before your first tool call on a multi-step task, send one or two
sentences saying what you will do first. Post a short update at each
milestone. Keep a TODO list for work with more than three steps, and
finish with what changed and what is left.
Not sure which AI model to use?
21 models · Personalized picks · 60 seconds
The TODO tool only helps if your agent has one. If you run through the API, you provide it as a function. In Codex and ChatGPT Work, check what the product already gives the model before you add your own.
Pattern 5: Carry reasoning forward with the Responses API
Tool calling on GPT-6.1 Sol now requires the Responses API.
OpenAI's reasoning guide says you can preserve reasoning across calls with previous_response_id, by attaching the response to a conversation, or by replaying the full response history yourself. When a task spans several calls, this keeps the model from rebuilding its context each time. Persisted reasoning works only within a model family, so a response from one family cannot carry its reasoning into a call to another. The guide also documents a reasoning.context setting with three values: auto, current_turn and all_turns. GPT-5.6 defaults to all_turns. The default for GPT-6.1 Sol is not stated, so I set all_turns explicitly on the follow-up call, as OpenAI's own GPT-6.1 Sol example does. The page for GPT-6.1 Sol also states that tool calling requires Responses, so an older Chat Completions agent loop needs a migration before it can use the new model with tools.
# Example only: continue a task without re-sending earlier reasoning.
first = client.responses.create(
  model="gpt-6.1-sol",
  reasoning={"effort": "medium"},
  input="Plan the migration of the orders table.",
)

followup = client.responses.create(
  model="gpt-6.1-sol",
  reasoning={"effort": "medium", "context": "all_turns"},
  previous_response_id=first.id,
  input="Now draft the first migration as SQL, with a rollback.",
)
The old advice to ask the model to summarize its prior decisions in a few bullets is optional now. It still helps a human reviewer, but it is not what carries the state.
Pattern 6: Set reasoning effort in the API, not in the prompt
I no longer use a "minimal reasoning" prompt. The API setting does that job.
For GPT-6, OpenAI's model guide maps low to routine tasks, medium to work that requires judgment, and high to difficult debugging. It says to keep xhigh or max only if the improvement justifies the added time and cost. (The "balanced starting point" and "low for latency-sensitive workloads" wording comes from OpenAI's GPT-5.6 migration list, not the GPT-6 guide.) OpenAI's migration advice is to replace minimal with low through the API parameter, not through prompt text. All three current Sol and Luna models default to medium. The supported range depends on the model:
Reasoning effort support
| Model | Supported values | Default |
|---|---|---|
| GPT-6.1 Sol | low, medium, high, xhigh, max | medium |
| GPT-6 Sol | none, low, medium, high, xhigh, max | medium |
| GPT-6 Luna | none, low, medium, high, xhigh, max | medium |
| GPT-6 Astra | low, medium, high, xhigh, max (none returns HTTP 400) | Not documented |
Source: OpenAI model pages for GPT-6.1 Sol, GPT-6 Sol, GPT-6 Luna and GPT-6 Astra, checked October 3, 2026.
For routine steps, such as adding a route or bumping a config value, try low. For work that needs judgment, stay at medium. Use high for difficult debugging. Move to xhigh or max only when your own evals show the gain justifies the added time and cost. More effort is not automatically better.
Pattern 7: Say how the answer should be written and how much to check
The model's defaults are a starting point, not your house style.
OpenAI notes that Astra tends toward detailed, formatted answers with lists, tables and Markdown, and may repeat phrases across sessions. It recommends specifying the writing style and structure your application needs. Its sample style guidance asks for clear, concise paragraphs, lists only when the content is parallel, sequential or easier to compare, plain language and active voice.
For coding, OpenAI also recommends calibrating how much testing a change needs: run the tests that fit the change, complete the required checks, and broaden or repeat testing only when new changes, failures or open concerns justify it. That keeps the agent from re-running everything after a one-line edit. My own advice is to put your build, test and lint commands, conventions and definition of done in AGENTS.md so every task inherits them. OpenAI's guidance is narrower: it says AGENTS.md should explain when particular documents and tests are relevant, and explicitly authorize safe routine workflows. It does not list build or lint commands or style rules.
Write the final message in plain paragraphs. Use a list only for the
list of changed files. Use backticks for file paths and symbols.
Run the tests that cover the change. Re-run more only if something fails
or you change more code.
Examples
One example prompt and one API example that put the patterns together. Neither is a measured result.
Examples, not benchmarks
Example A is a starting point I would use for a coding agent, and I have not run a controlled test of it against alternatives. Example B is an API sketch, not a tested pipeline. Test both against your own tasks, and adjust the paths and commands to your repo.
| Example | Use case | Patterns used |
|---|---|---|
| Bug fix agent | A scoped fix in an existing codebase | 1, 3, 4, 7 |
| Long-running API task (code, not a prompt) | A multi-call job through the Responses API | 5, 6 |
Example A: scoped bug fix
Goal: Fix the failing checkout test and leave the repo in a working state.

Done means:
- The failing test passes and the checkout test suite is green.
- You ran the changed code path and checked the output.
- Your final message lists the files you changed and anything I should review.

Without asking, you may: read files, search the repo, run tests and
linters, and edit files under src/checkout.
Ask first before: changing dependencies, editing CI config, touching
files outside src/checkout, or deleting data.

Before your first tool call, send one or two sentences saying what you
will do first. Post a short update at each milestone. Keep a TODO list
if the work has more than three steps.

Match the existing code style. Write the final message in plain
paragraphs, with a list only for the changed files.
Example B: continuing a task through the Responses API (an API example, not a prompt)
Use the code in pattern 5. Pass previous_response_id on each follow-up call, set reasoning.context to all_turns, keep the effort at medium, and move a step to low only if it is routine and your tests are strong.
Measuring results
Prompt changes need evals. These are the numbers I would track.
Metrics to monitor
- 1Task completion rate without human intervention
- 2Time to a first passing run
- 3Edit revert rate and hotfix rate
- 4Token and tool-call cost per successful task
These are my suggestions, not OpenAI's. They matter most when you shorten an old prompt (pattern 2) or lower the reasoning effort (pattern 6), because both changes can hide a regression until you measure it.
How this post was sourced
Prompting guidance in this post is paraphrased from OpenAI's published pages, which I checked on October 3, 2026. Model names, prices and reasoning effort values match the repo's verified model data and OpenAI's model pages. Some of OpenAI's guidance is written for GPT-6 Astra specifically, and some comes from the GPT-5.5 and GPT-5.6 sections of the Using GPT-6 page. Where a pattern is my own recommendation, I say so. I have not run my own benchmark of these patterns, and I could not verify OpenAI's guidance on every model separately. Check the linked pages for current wording.
Sources
- OpenAI: A model guide for the GPT-6 family
- OpenAI: Rethinking skills and prompts for GPT-6 Astra
- OpenAI: Using GPT-6 (GPT-5.5 and GPT-5.6 sections cited above)
- OpenAI: Reasoning models guide, including the reasoning.context section
- OpenAI: GPT-6.1 Sol model page
- OpenAI: GPT-6 Sol model page
- OpenAI: GPT-6 Luna model page
- OpenAI: GPT-6 Astra model page
FAQ
How do I prompt GPT-6 differently from GPT-5?
Write shorter prompts. OpenAI scopes its warning about overly specific guidance to Astra ("Guidance that helps Sol or Luna may overconstrain GPT-6 Astra"), so for Sol and Luna treat it as a hypothesis to test. Define the goal, what done means, and which actions the model may take on its own. I would also remove step-by-step scaffolding, repeated "ask first" rules (OpenAI's GPT-5.6 guidance warns they trigger needless approvals) and prompt-level "minimal reasoning" instructions. OpenAI's migration advice is to replace minimal with low through the API parameter.
What reasoning effort should I use with GPT-6.1 Sol?
Start at medium, which is the default. OpenAI's GPT-6 model guide maps low to routine tasks, medium to work that requires judgment and high to difficult debugging, and says to keep xhigh or max only if the improvement justifies the added time and cost. GPT-6.1 Sol supports low, medium, high, xhigh and max, and does not support none or minimal. Raise the setting only if your own evals show a gain.
Do I still need the Responses API for GPT-6?
For tool calling with GPT-6.1 Sol, yes. The model's page says tool calling requires the Responses API. The Responses API also lets you carry reasoning from one call to the next with previous_response_id or by passing the earlier output items back in. Persisted reasoning works only within a model family.
Founder of Spectrum AI Labs — testing AI tools and models, and writing up what actually ships.
More about Paras →Need Help Moving Your Prompts to GPT-6?
We help engineering teams test and tune prompts for current models. Get a free consultation to look at your specific workflow.