Claude Code Review reviews proposed code changes before they are merged. A pull request (PR) is that proposed set of changes. Launched March 9, 2026, the service uses AI agents, independent workers that examine code in parallel, and checks their findings before posting. Large or complex changes get more agents and a deeper review. In Anthropic's internal use, 84% of PRs with over 1,000 changed lines received findings, averaging 7.5 issues. Engineers there marked less than 1% of findings incorrect. Those figures describe internal use and feedback. Reviews average $15-25, billed separately from Team and Enterprise plans. Approval stays with humans.
- Claude Code Review launched March 9, 2026. Large or complex changes get more agents and a deeper review; simple changes get a lighter review.
- Engineers at Anthropic marked less than 1% of findings incorrect during internal use. This is feedback on findings, not a measured false-positive rate.
- In Anthropic's internal use, 84% of large PRs (over 1,000 changed lines) received findings, averaging 7.5 issues. This measures PRs with findings, not the share of bugs caught.
- Reviews average $15-25, billed by token usage separately from the included usage on Claude Team and Enterprise plans.
- Before Claude Code Review, only 16% of PRs at Anthropic received substantive review comments. After enabling it, 54% did.
- 41% of all code written in 2025 was AI-generated, and 96% of developers do not fully trust AI-generated code accuracy.
- A production bug costs 30x more to fix than one caught during development. Enterprise downtime runs $300,000+ per hour.
- Claude Code Review will never approve a PR. The merge decision always stays with a human reviewer.
AI coding tools made writing code roughly 6x faster. Nobody upgraded the review process to match. PR backlogs at some teams ballooned past 150. Diffs that used to take days to properly review started getting approved in half an hour. Claude Code Review is Anthropic's answer to that imbalance.
I checked the official launch post and documentation. The comparison below uses the vendors' documented features and billing, checked on October 2, 2026.
The Review Problem in Numbers
Code volume went up. Review capacity didn't.
GitClear tracked this: code churn (code rewritten within two weeks) went from 5.5% in 2020 to 7.9% in 2024. It's expected to double again in 2026. Duplication rose eightfold. Refactored lines dropped from 24.1% to 9.5%. Teams are writing more code faster and cleaning it up less.
The downstream effect: teams with heavy AI adoption merged 98% more PRs, but review times went up 91%. The throughput increase landed entirely on reviewers who were already stretched.
A few numbers that frame how bad this is:
- 75% of developers spend up to 5 hours per week on code review
- 41% of all code written in 2025 was AI-generated
- 96% of developers don't fully trust the functional accuracy of AI-generated code
- Human defect detection degrades sharply past 400 lines of diff — and a single AI feature can blow past that in one prompt
- Technical debt increases 30-41% after AI tool adoption
The Cost of Missing Bugs
A bug found after release costs 30x more to fix than one caught during development. Enterprise downtime runs $300,000+ per hour. CISQ estimates software bugs cost the US economy $2.41 trillion per year. The review step is where most of those bugs should get caught.
The Pragmatic Engineer put it simply: "The natural bottleneck on all of this is how fast code can be reviewed." Anthropic reports that the share of PRs receiving substantive review comments rose from 16% to 54% with Code Review. That measures comments received; it does not show how thoroughly each PR was reviewed.
How Claude Code Review Actually Works
Review effort scales with the size and complexity of the change.
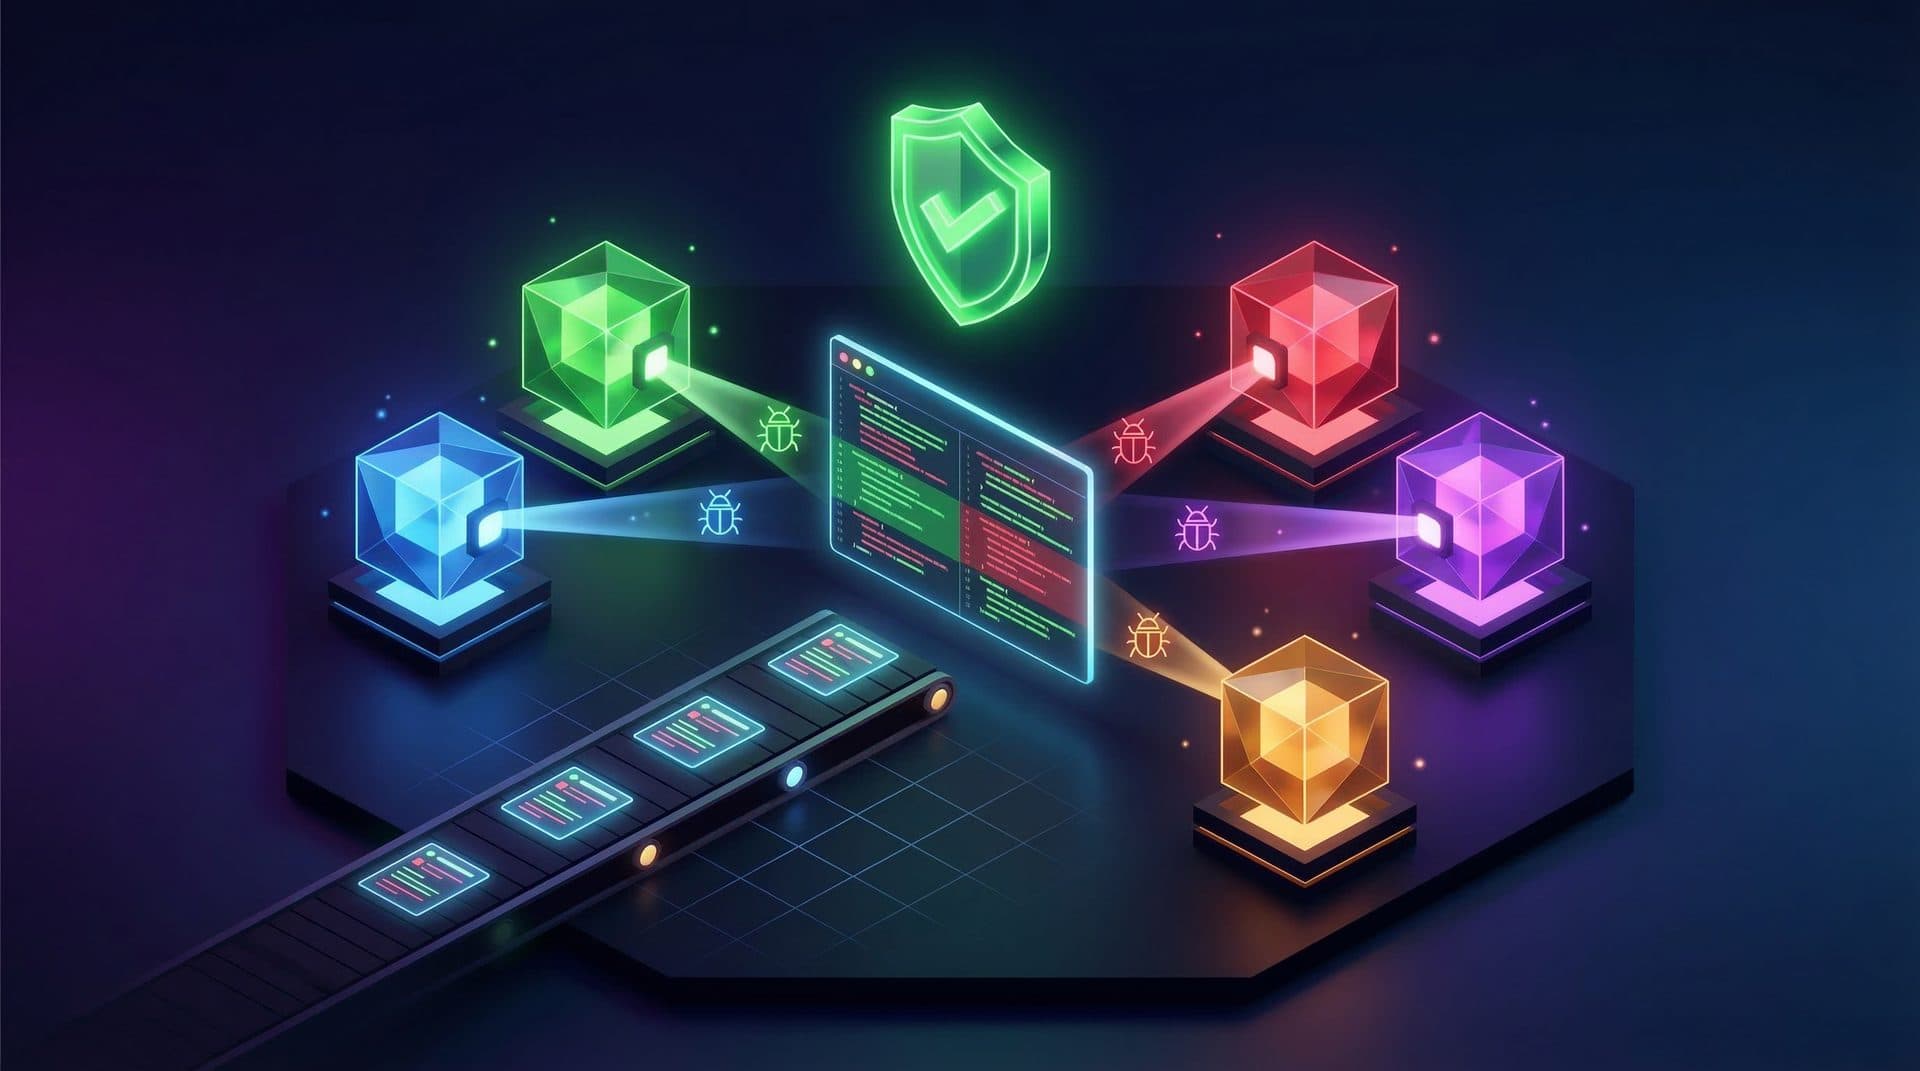
The managed service sends multiple AI agents to examine the code changes and surrounding code in parallel. Large or complex changes get more agents and a deeper review. Simple changes get a lighter pass. Anthropic does not describe a fixed number of agents for every PR.
The Managed Review Process
- 1Agents examine the changes and surrounding code in parallel to find possible bugs
- 2A verification step checks possible issues against how the code behaves
- 3Repeated findings are combined and ranked by severity
- 4The review posts a summary and comments on the affected lines in GitHub
The verification step checks whether a suspected issue is supported by the code before posting it. The separate Code Review plugin documents a fixed reviewer setup and confidence thresholds. Those details do not describe this managed service.
What matters to a team is whether the comments help them fix code. Anthropic reports that its engineers marked less than 1% of findings incorrect during internal use. That is feedback on the findings they saw, rather than a controlled accuracy test against other tools.
Choose When Reviews Run
- Once after PR creation: On an enabled repository, review when the PR opens or is marked ready for review.
- After every push: Review updates to a PR on an enabled repository when this setting is selected.
- Manual: Start a top-level comment with
@claude reviewfor one review of an open PR. You need write, maintain, or admin permission. Use@claude review alwaysto also subscribe a PR to later push reviews.
Fork PRs require an explicit review request each time; pushes do not trigger reviews on them. If your organization membership is private, manual requests also require you to be added directly as a repository collaborator, or to make that membership public. See the command requirements before relying on manual reviews.
Findings appear as inline GitHub comments with severity labels. On a PR subscribed to push reviews, the next review can resolve a thread after the issue is fixed. In other modes, request another review with @claude review.
The Numbers: What It Catches and How Often
These figures come from Anthropic's internal use, reported at launch.
Not sure which AI model to use?
21 models · Personalized picks · 60 seconds
| PR Size (Lines Changed) | PRs Receiving Findings | Average Issues per Review |
|---|---|---|
| Large (over 1,000 lines) | 84% | 7.5 issues |
| Small (<50 lines) | 31% | 0.5 issues |
In Anthropic's internal use, Code Review produced findings on 84% of PRs with over 1,000 changed lines. This tells us how often a review produced findings. It does not measure the share of all bugs caught or prove that every finding was correct. The launch post gives no figures for medium-sized PRs.
The increase from 16% to 54% means more PRs at Anthropic received substantive comments. A PR without comments may still have been reviewed, so this statistic alone cannot establish how much code received a thorough review.
Average Review Time
Anthropic reported about 20 minutes per review on average in its testing. Review time varies with the change. Choose your repository's trigger setting with both turnaround time and repeat review costs in mind.
Pricing: $15-25 Per Review, Token-Based
Billed separately from your Claude plan.
Claude Code Review costs $15-25 per review on average, scaling with PR size and complexity. It's billed via token usage, separate from your plan's included usage.
- Availability: Research preview for Claude Team and Enterprise customers
- Billing: Token-based, not per-seat. Admins can set a spend cap.
- Managed service access: Team and Enterprise plans. Pro and Max users can review changes locally in Claude Code, but those plans do not include this managed PR service.
For context: fixing a production bug costs 30x more than catching it during development. If Claude Code Review catches even one bug per sprint that would have reached production, the math works out fast. A single hour of enterprise downtime ($300K+) pays for 12,000-20,000 reviews.
How It Compares to Copilot and Bugbot
Documented review behavior and billing, checked October 2, 2026.
| Tool | How It Reviews | How It Starts | Where It Runs | Billing |
|---|---|---|---|---|
| Claude Code Review | Parallel agents; effort scales with the PR; findings checked before posting | Repository setting: creation, pushes, or manual comment; forks need explicit requests | Anthropic infrastructure; comments on GitHub PRs | Token usage; $15-25 average per review, billed separately |
| GitHub Copilot | Mix of models; agents gather repository context | Assign Copilot as reviewer, or enable automatic reviews | GitHub and supported IDEs; context gathering uses Actions runners | AI credits plus Actions minutes on GitHub-hosted runners; eligible legacy annual plans use premium requests |
| Cursor Bugbot | Analyzes code changes and comments with suggested fixes | Updates to enabled PRs, or cursor review / bugbot run comments; settings can limit runs | Connected GitHub, GitLab, Bitbucket, or Azure DevOps repositories | Usage-based; additional reviews can bill from on-demand spend; older plans have legacy terms |
The cited official pages do not provide a controlled accuracy comparison between these tools. Anthropic's internal findings data cannot establish an accuracy winner.
GitHub Copilot uses a mix of models and gathers repository context through agents. Its current documentation describes AI credits, units of AI usage, and Actions minutes, time spent on GitHub-hosted automation machines. These machines gather code context for the review. Self-hosted runners do not consume Actions minutes. Included allowances may cover some usage; additional usage can cost money. Eligible Pro and Pro+ subscribers who kept an older annual plan use legacy premium-request allowances.
Cursor Bugbot now uses usage-based billing. Team reviews bill from on-demand spend, and additional reviews after included usage can incur charges. Before the May 2026 pricing change, Cursor plans included limited reviews, with separate paid terms described on the legacy pricing page. Check which billing terms apply to your account.
If you already use Claude Code, the managed review service can use your repository's CLAUDE.md instructions. Review usage is still billed separately from the plan's included usage.
Setting It Up
An organization owner enables repositories and chooses their review triggers.
Getting Started with Claude Code Review
- 1Requirement: Claude Team or Enterprise plan, without Zero Data Retention enabled
- 2An organization Owner enables Code Review in admin settings, installs the GitHub App, and selects repositories
- 3Set a spend cap if you want to limit review costs
- 4Choose each repository's trigger: once after PR creation, after every push, or manual
- 5For a manual review of an open PR, start a top-level comment with @claude review; write, maintain, or admin permission is required
- 6Findings appear as inline PR comments with severity labels
- 7After fixing an issue, let a subscribed push review run or request another review so Claude can check it
The service reads CLAUDE.md, your shared project instructions, and flags newly introduced violations as minor findings. For review-specific rules, use REVIEW.md. We covered project instructions in our Claude Code guide.
What Claude Code Review Won't Do
Check managed service access and costs before enabling reviews.
Worth knowing upfront:
- It won't approve PRs. Ever. The merge decision stays with a human. This is a deliberate design choice, not a missing feature.
- Managed service access is limited. You need Team or Enterprise, and organizations with Zero Data Retention enabled cannot use it. Local code review in Claude Code is a separate option on other plans.
- The managed service reviews GitHub PRs. Check whether this fits where your team hosts its code.
- Research preview. It's not GA yet, so expect rough edges.
- Cost adds up on high-volume repos. At $15-25/review, a repo with 20 PRs/day costs $300-500/day. Set the spend cap.
Is It Worth It?
Depends on your team size, PR volume, and how much you trust your current reviews.
I've used a few AI review tools over the past year. Most of them generated so many false positives that our team stopped reading the comments within a week. That's the bar Claude Code Review has to clear: not just finding bugs, but being right often enough that people keep paying attention.
The verification step checks possible issues before the review posts them. Anthropic's engineers marked less than 1% of findings incorrect in internal use. I would test the service on my team's own PRs and check whether the comments are useful enough to justify the review bill.
It makes sense if:
- Your team ships 10+ PRs/day and review is the bottleneck
- You've had bugs reach production that should have been caught in review
- You already use Claude Code and want review integrated into the same ecosystem
- You have a CLAUDE.md with project-specific rules you want enforced
It doesn't make sense if:
- You're a solo developer or small team with <5 PRs/day — the cost adds up without enough volume to justify it
- Your code is hosted outside GitHub
- You need reviews covered entirely by included usage. Claude bills these reviews separately; check Copilot's allowances and Bugbot's usage terms before choosing either.
The bigger context: 95% of developers use AI tools weekly. 41% of code is AI-generated. We automated writing. We automated testing (partly). Review was the gap, and it was getting wider every quarter. Whether $15-25/review is the right price for your team depends on a simple question: how many bugs made it to production last month that a second pair of eyes would have caught?
For a comparison of the models powering these tools, check our task-by-task AI model guide. Or if you want a quick recommendation for your specific workflow, take our AI Model Picker quiz.
Frequently Asked Questions
What is Claude Code Review?
Claude Code Review is Anthropic's managed pull request review service, launched March 9, 2026. AI agents examine changes in parallel and check possible issues before posting comments. Large or complex changes get more agents and a deeper review; small, simple changes get a lighter review.
How much does Claude Code Review cost?
Claude Code Review costs $15-25 per review on average, billed via token usage. It scales with PR size and complexity. It is billed separately from your Claude plan's included usage. Available as research preview for Claude Team and Enterprise customers.
How does Claude Code Review compare to GitHub Copilot code review?
Claude Code Review uses parallel agents whose review effort scales with the change. It runs on Anthropic infrastructure and bills by token usage. Copilot uses a mix of models and gathers repository context through GitHub Actions. Its current billing uses AI credits and, with GitHub-hosted runners, Actions minutes; eligible legacy annual plans use premium-request allowances. Extra usage can cost money. The cited official pages do not provide a controlled accuracy comparison between these tools.
Can Claude Code Review approve pull requests?
No. Claude Code Review posts findings and leaves approval to humans. If a pull request is subscribed to reviews after pushes, a later review can resolve its comment threads when the issue has been fixed. Otherwise, request another review with a top-level @claude review comment.
Founder of Spectrum AI Labs — testing AI tools and models, and writing up what actually ships.
More about Paras →Not Sure Which AI Coding Tool Fits Your Workflow?
Take our free AI Model Picker quiz to get a personalized recommendation based on your use case, budget, and team size.